
The catalog is where an AI agent finds the right table to answer a business question, without it, the agent guesses. AWS Glue Data Catalog is that catalog for AWS data lakes, warehouses, and databases, but it was built to answer a narrower question than that one, the same one Atlan, Alation, Collibra, and DataHub each answer differently outside AWS’s boundary. Crawlers write to it, ETL jobs read from it, and query engines like Athena and Redshift Spectrum check it before they run. That’s a metadata store built for engines and pipelines, not for a person, or an agent, to ask what a column means or whether a table is safe to trust. Whether that gap has actually started closing is the more useful question.
This serverless service integrates with AWS services like Athena and Redshift to support structured and semi-structured data, enabling governance, ETL, flexible querying, and automated schema discovery for cataloging.
AWS Glue is one of the most popular cloud-based ETL solutions, especially if your data infrastructure is mostly hosted on AWS. The AWS Glue Data Catalog acts as a metadata store for AWS services and any services outside of AWS that are compatible with a Hive metastore.
What is AWS Glue?
AWS Glue is a cloud-based ETL tool that allows you to store source and target metadata using the Glue Data Catalog, based on which you can write and orchestrate your ETL jobs either using Python or Spark.
AWS Glue offers a great alternative to traditional ETL tools, especially when your application and data infrastructure is hosted on AWS.
Glue is a fully managed ETL service that would make it easier to categorize, clean, transform, and transfer data between different data stores. These data stores could be EC2 machines, object storage, different types of databases, caches, and so on.
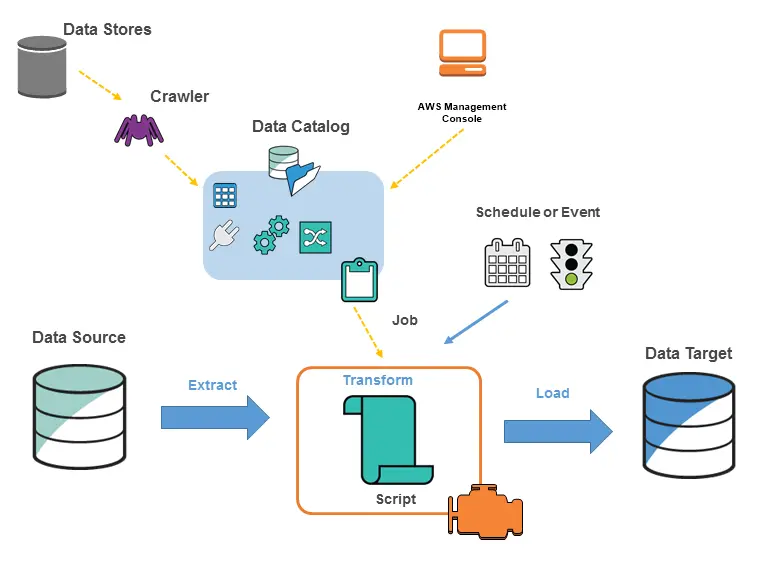
AWS Glue Environment. Source: AWS Glue Developer Guide.
AWS Glue use cases
AWS Glue isn’t just an ETL tool; it is a lightweight job orchestrator, a data catalog solution, and much more.
AWS Glue can help you
- Extract, transform, and load data from various sources to various targets, either using out-of-the-box patterns or writing your own.
- Run serverless queries against your data lake in Amazon S3 using Redshift Spectrum or Amazon Athena.
- Understand your data by storing and organizing metadata in a Hive-compatible metastore using AWS Glue Data Catalog.
How this fits in the Context Layer
Data Catalog is one piece of the broader Context Layer: the bedrock that makes every AI agent in your business useful, accurate, and trustworthy. It connects to:
- Data Discovery: the surface where an agent picks the right asset and a human verifies the agent’s pick.
- Data Governance: the rules an agent must respect when it answers, inherited automatically from the catalog.
- Metadata Management: the continuous enrichment (descriptions, lineage, quality signals) that keeps an agent’s context fresh.
Together, these surfaces give every agent (Genie, Cortex, Claude, Cursor, and the next one) the same governed view of your business.
How does AWS Glue work?
AWS Glue depends on the AWS Glue Data Catalog, which maintains metadata about sources and targets. Glue executes ETL jobs based on this metadata to move data from sources to targets.
Data sources supported by AWS Glue
Glue supports a wide variety of data sources, both batch-based and stream-based. Glue integrates directly with AWS services, such as S3, RDS, Kinesis, DynamoDB, and DocumentDB. It supports any database or data warehouse as a source that can be exposed using a JDBC connection. Apart from that, AWS Glue also supports MongoDB and Apache Kafka as data sources.
Data targets supported by AWS Glue
AWS Glue supports, more or less, all the sources as targets, too, such as Amazon S3, RDS, MongoDB, DocumentDB, and any database that can be exposed using a JDBC connection.
Glue Data Quality: AWS introduced ML-driven data quality monitoring for the Glue Data Catalog in August 2024. Two years on, it’s a standard part of the platform rather than a new feature: rule-based and ML-powered checks flag unexpected data patterns across regions, and it bills at the same DPU-hour rate as any other Glue job (see pricing below). More on the original launch is on AWS’s blog here.
Understanding AWS Glue’s architecture
AWS Glue is made up of several individual components, such as the Glue Data Catalog, Crawlers, Scheduler, and so on.
AWS Glue uses jobs to orchestrate extract, transform, and load steps. Glue jobs utilize the metadata stored in the Glue Data Catalog.
These jobs can run based on a schedule or run on demand. You can also run Glue jobs based on an event trigger, hence laying the foundation for event-driven ETL pipelines.
AWS Data Catalog
AWS Glue uses a Hive-compatible metastore as a data catalog. The data catalog is essential to ETL operations. Before running your job, you need to catalog the source and target metadata.
Because of its Hive compatibility, the AWS Glue Data Catalog can also be used as a standalone service in combination with a non-AWS ETL tool.
AWS Glue ETL operations
After ensuring that the data stores are crawled properly to get the latest metadata information into the AWS Glue Data Catalog, you are ready to use Glue to move data around within your data ecosystem.
The data moving requires a Glue job, which uses a Python, Spark, or Ray environment to execute. Your execution speed, resources, and costs will differ depending on your choice.
AWS Glue crawlers
Crawlers are scripts to get the latest metadata from a data store. If you are using a database as a data store, think of crawlers as running a SELECT query on the information_schema. Crawlers can either be run on a schedule or on demand.
Crawlers utilize predefined classifiers to determine the schema of your data. This schema is then replicated in the Glue Data Catalog as closely as possible. Crawlers can help you get the metadata from a variety of data stores.
AWS Glue Management Console
Like all other services, AWS Glue can be managed via multiple interfaces. The most popular and easy-to-use among these interfaces remains the Management Console.
Using the Management Console, you can work with jobs, crawlers, classifiers, sources, targets, etc. Alternatively, you can also use the API or the SDK specific to your programming language or development framework.
Job scheduling and orchestration
For scheduling, AWS Glue uses cron expressions. Most advanced workflow management tools and orchestration engines like Airflow and Prefect also use some variants of cron expressions to schedule jobs.
With the ability to define several types of dependencies between jobs, you can create complex ETL workflows, imitating DAGs (directed acyclic graphs), which are essential to handle real-world ETL scenarios.
AWS Glue Data Catalog explained
AWS Glue Data Catalog is a Hive-compatible metastore used by AWS Glue as a uniform repository of metadata coming from disparate systems.
In addition to being a data catalog, AWS Glue Data Catalog also offers audit and data governance capabilities.
AWS Glue Data Catalog and Apache Iceberg
The biggest change to the Data Catalog since 2022 isn’t a new AWS service. It’s Iceberg.
AWS Glue Data Catalog now runs a native Iceberg REST catalog: an endpoint (https://glue.{region}.amazonaws.com/iceberg) that speaks the Apache Iceberg REST specification directly, so any Iceberg-compatible engine, Spark, Athena, or Trino among them, can read and write against Glue without a separate catalog service sitting in between. It supports both Iceberg table specs, v1 and v2, defaulting to v2.
Two more Iceberg capabilities reached general availability in November 2025:
- Iceberg v3 support: deletion vectors and row lineage, plus Iceberg-backed materialized views, tracked natively in the Data Catalog.
- Catalog federation to remote Iceberg-REST-compatible catalogs: Snowflake Polaris, Databricks Unity Catalog, and other Iceberg-REST catalogs can register directly against Glue’s endpoint, without copying the underlying data into Glue’s own storage first.
That federation point matters more than it sounds. It means Glue Data Catalog no longer has to be the catalog of record for an Iceberg table to be reachable through it. A table cataloged in Unity Catalog or Polaris can now be queried from the AWS side through federation, which is a meaningfully different position than the AWS-only story from a year ago.
Iceberg matters here only as far as it touches the Data Catalog itself. For the Spark configuration, namespace-to-database mapping, and cross-platform setup, Atlan’s guide to Apache Iceberg and AWS Glue goes deeper.
AWS Glue Data Catalog key features
- Persistent, Hive-compatible metastore for enabling ETL operations
- Fine-grained (column, row, and cell-level) access control through AWS Lake Formation, layered on top of IAM rather than replacing it
- Comprehensive audit and data governance for compliance
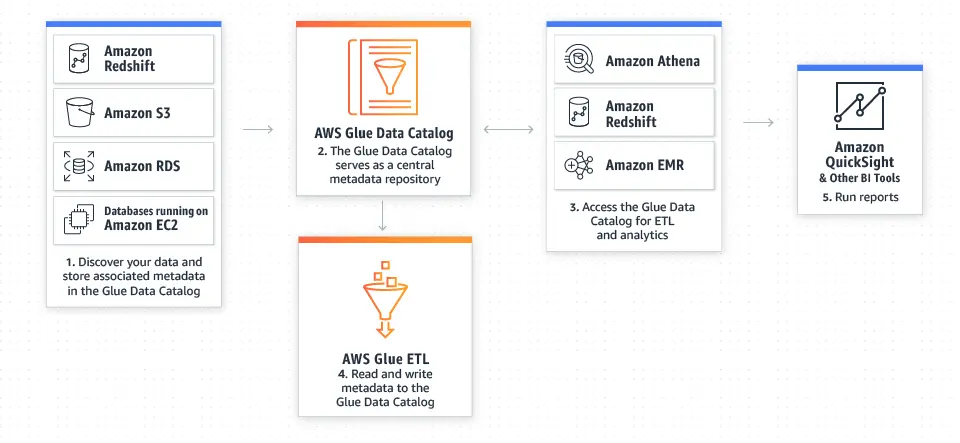
AWS Glue Data Catalog Architecture. Source: AWS Glue.
AWS Data Catalog use cases
You can use the AWS Glue Data Catalog with various services in the following ways:
- Creating a Data Lake using AWS Lake Formation: AWS Lake Formation is AWS’s managed data lake service, built on top of AWS Glue Data Catalog. Beyond moving data between layers, Lake Formation is also where fine-grained, column, row, and cell-level, permissions live: LF-Tag-based access control, multi-account and cross-organization sharing, and a hybrid access mode that lets teams run Lake Formation permissions and plain IAM side by side while migrating policies over, instead of cutting across all at once. Since November 2025, Lake Formation can also federate to Redshift, external Hive metastores, and Amazon S3 Tables without moving the underlying data.
- Querying External Data using Athena & Redshift Spectrum: After storing schema information and other metadata for an external data source, you can use Athena or Redshift Spectrum to query the data source directly. The AWS Glue Data Catalog retains the schema information, which helps the query engine read data from the data source.
- Data Processing & Analysis using Amazon EMR: In scenarios where you have to perform process large amounts of data or complex data analysis, you can take advantage of EMR, which gives you EC2 machines that run in a Hadoop ecosystem, giving you an easy way to write and execute Spark or PySpark code.
- Using Glue Data Catalog as a Standalone Metastore: AWS Glue Data Catalog can be used as a standalone service with any data store compatible with Apache Hive. So, even if your data infrastructure doesn’t completely lie on AWS, you can still take advantage of AWS Glue Data Catalog as your central metadata repository to enable ETL operations using a separate ETL tool.
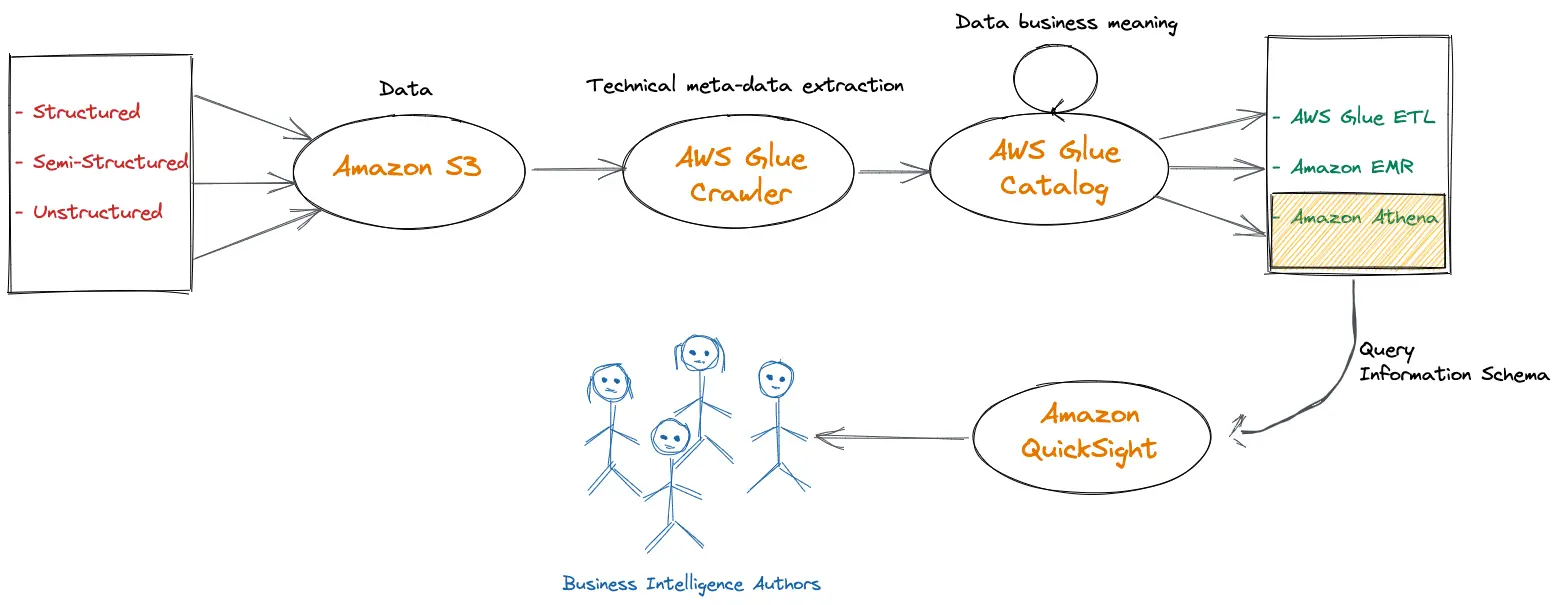
AWS Glue Data Catalog in AWS ecosystem. Source: AWS Glue.
Is AWS Glue Data Catalog ready for AI agents?
Split this into what’s actually shipped, what AWS just previewed, and what still needs a different tool entirely.
Verified and GA today:
- A persistent, Hive-compatible metastore that any Hive-compatible engine can read.
- A native Iceberg REST catalog, Iceberg v3, and federation to remote Iceberg catalogs (above).
- Fine-grained Lake Formation permissions layered on IAM, with hybrid access mode for incremental rollout.
- Published, current DPU-hour pricing (below).
In motion, and worth naming precisely because it’s new: in June 2026, AWS announced a preview of business context and semantic search for Glue Data Catalog. It lets teams attach glossary terms and custom metadata fields to tables, then search by what the data means rather than what it’s named, through a new Glue Search API built for that purpose. AWS also shipped a first-party MCP plugin, aws-data-analytics, through its Agent Toolkit for AWS, so that any MCP-compatible agent, including Claude Code, Kiro, Cursor, and Codex, can connect to it with close to no setup.
That’s a real, AWS-branded answer to “can an agent read this catalog at runtime instead of a person reading it in a console.” It’s also, as of this writing, Preview, not GA, and live in four AWS regions: us-east-1, us-east-2, us-west-2, and eu-west-1. Treat it as in motion, not as a capability you’d plan a production workflow around yet. Separately, there are unofficial, non-AWS-published MCP projects for Glue circulating on GitHub; they predate this launch, aren’t first-party, and aren’t a substitute for it.
Not ready, and not close to a version bump: cross-account governance fragmentation, no collaboration features for teams, no data mesh constructs, and crawler-based schema inference that samples data rather than reading all of it. None of these are Iceberg- or AI-agent-shaped problems. They’re structural, and Atlan’s rundown of AWS Glue Data Catalog’s limitations covers all six in depth.
Current AWS Glue Data Catalog pricing
AWS Glue bills most operations, ETL jobs, crawlers, statistics generation, table optimization, materialized view refreshes, and Glue Data Quality checks, at $0.44 per DPU-hour; Spark and Spark Streaming ETL job runs carry a two-DPU minimum per run. The Data Catalog itself is priced separately from compute: storing the first million objects (databases, tables, partitions) is free, and each additional 100,000 objects costs $1.00 per month. Catalog requests follow the same pattern, with the first million each month free.
For a team already committed to AWS, that’s a low floor to get a working metastore running. It’s also usage-based rather than fixed, which is worth knowing before comparing it against a subscription-priced catalog like Atlan; the full cost comparison lives in Atlan’s AWS Glue Data Catalog + Atlan guide.
AWS Glue Data Catalog: Benefits and limitations
There are real benefits to using AWS Glue Data Catalog. It:
- Is serverless: you only pay for what you use, with no resources to provision in advance.
- Has out-of-the-box cataloging and ETL capabilities: built-in classifiers handle crawling, and built-in transforms cover common ETL patterns.
- Offers built-in workflow and orchestration: Glue can chain your ETL workloads on its own, though the integration with external orchestration tools like Airflow isn’t as smooth.
It also has real limits, and they’re structural rather than cosmetic: schema inference that samples data instead of reading all of it, cross-account governance that doesn’t propagate cleanly, no collaboration features for teams working on the same assets, and no native data mesh constructs. Atlan’s guide to AWS Glue Data Catalog’s limitations covers all six, and why each one exists.
What is AWS Glue Data Catalog?
Using crawlers to populate AWS Glue Data Catalog
What are AWS Glue crawlers?
You need AWS Glue Data Catalog to have the metadata information for source and target schemas to perform ETL operations. AWS Glue crawlers are scheduled or on-demand jobs that can query any given data store to extract scheme information and store the metadata in the AWS Glue Data Catalog. Glue Crawlers use classifiers to specify the data source you want it to crawl.
General workflow of how crawlers populate AWS Data Catalog
A Glue Crawler gets the metadata from a data source and writes to the AWS Glue Data Catalog in the following manner:
- Glue uses a built-in or custom classifier to determine the data’s format, schema, and other properties. In SQL terms, imaging this being a
SELECTquery on a sample of the actual data and approximating the table’s structure based on the sample. - Glue Crawler groups the data into tables or partitions based on data classification. If the crawler is getting metadata from S3, it will look for folder-based partitions so that the data can be grouped aptly.
- Glue pushes the data into the AWS Glue Data Catalog, after which the crawled datastore is ready to be used in ETL operations.
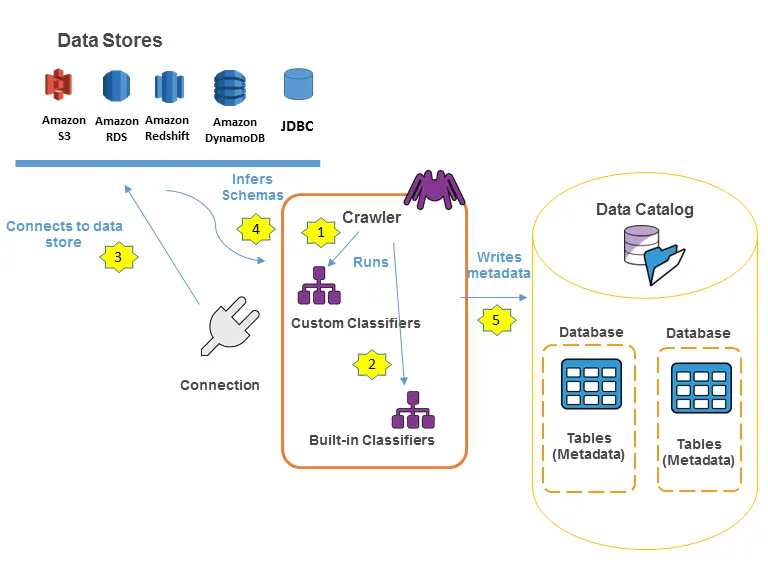
Work flow diagram populating AWS Glue Data Catalog. Source: AWS Glue Developer Guide.
Glue offers a variety of classifiers that cover most of the popular data stores. However, if you don’t find your data source covered by the built-in classifiers, you can write your own classifier to crawl the data store.
Learn more - Simplify data discovery for business users with AWS Glue data catalog
AWS Glue vs. EMR
AWS Glue and EMR both provide data computation and processing services. Both these services overlap in many of the features while offering something unique also because of the way they’ve been implemented. AWS Glue is a serverless ETL service, while AWS EMR uses EC2 instance clusters to create a Hadoop ecosystem for processing large amounts of data.
When you don’t know your data processing requirements, it’s better to use AWS Glue as it has a pay-as-you-go model. With EMR, you’d have to dedicate money to infrastructure that you may not even end up using. Moreover, EMR only solves the computation and processing problem; it doesn’t offer any data cataloging or workflow orchestration service. AWS Glue has the edge over EMR on this too.
EMR would make sense for you to use if you have a very good idea about the volume of data you’ll be processing, along with the type and complexity of the transforms you’ll be performing on that data.
Comparing AWS Glue Data Catalog against other options
Everything above describes what Glue Data Catalog does today, gaps included. Whether that’s enough depends on what else is in your stack: a team running Redshift, S3, and Athena and nothing else has a very different answer than one that also runs Snowflake, Databricks, and a BI layer on top. If you’re weighing Glue against Atlan, Amundsen, DataHub, or another candidate, Atlan’s tool-by-tool comparison puts them side by side on the same criteria: connectors, hosting, governance, usability, and extensibility.
Conclusion
AWS Glue Data Catalog is still what it always was: a serverless, Hive-compatible metastore that’s the obvious default if your data infrastructure already lives in AWS. What’s changed since 2022 is how far that default now reaches. A native Iceberg REST catalog, federation to catalogs outside AWS entirely, and a first-party, if still Preview, path for AI agents to query it directly all move Glue Data Catalog closer to a multi-cloud, multi-engine world than it was two years ago.
It isn’t there yet for every workload. Multi-cloud governance, team collaboration, and data mesh constructs remain gaps Glue doesn’t close on its own. If your data infrastructure is fully on AWS and you have the technical depth to run it, Glue Data Catalog is a capable, cost-effective place to start. If it isn’t, or once it stops being enough, that’s a different question, and the rest of this site covers it.
Atlan plus AWS Glue Data Catalog
Atlan connects to AWS Glue Data Catalog and pulls its metadata into a single place alongside every other system in your stack, then adds what Glue doesn’t do on its own: business glossaries, embedded collaboration, cross-platform lineage, and governance that holds outside AWS’s boundary. Glue keeps doing what it does well as the technical metastore for AWS-native operations; Atlan is the layer teams and agents outside that boundary use to find and trust the same data. The full comparison, including a feature-by-feature table and pricing model, lives here.
One customer example: Nasdaq uses Atlan across its AWS data infrastructure, including Glue transformations, to govern data at scale.
If your data team runs on AWS, see how Atlan works with Glue, or go straight to talk to us.
Some more resources on how to connect Atlan with AWS Glue Data Catalog:
FAQs about AWS Glue Data Catalog
1. What is the purpose of the AWS Glue Data Catalog?
The AWS Glue Data Catalog serves as a central metadata repository for managing data across various AWS services and Hive-compatible platforms. It enables data discovery, search, and schema management, and it’s what ETL jobs and query engines like Athena and Redshift read from before they run.
2. How can I set up the AWS Glue Data Catalog?
To set up the AWS Glue Data Catalog, configure a database in the AWS Glue console, then use crawlers to scan data sources and update the catalog with metadata. AWS provides options to integrate with various data stores and customize crawler settings based on data structure.
3. What are the benefits of using AWS Glue for data cataloging?
AWS Glue Data Catalog centralizes metadata management and automates schema inference through crawlers, so data assets stay organized without manual entry. Integration with AWS analytics services like Athena and Redshift extends that into query performance and ETL workflows directly.
4. How does AWS Glue Data Catalog integrate with data lakes or warehouses?
AWS Glue Data Catalog integrates with data lakes on Amazon S3 and data warehouses like Amazon Redshift, allowing you to create a unified view of all data assets. By cataloging metadata, it ensures consistent data access, supports query optimization, and simplifies ETL operations.
5. What security features does the AWS Glue Data Catalog offer?
Fine-grained access control, at the column, row, and cell level, comes from AWS Lake Formation layered on top of IAM policies, not from IAM alone. Metadata is encrypted at rest and in transit, and Lake Formation’s hybrid access mode lets teams adopt these finer-grained permissions incrementally instead of migrating every policy at once.
6. Can the AWS Glue Data Catalog be used with on-premises data sources?
Yes, AWS Glue Data Catalog can be configured to work with on-premises data sources through compatible connectors and AWS Direct Connect, allowing you to manage and catalog metadata across hybrid environments.
7. Does AWS Glue Data Catalog support Apache Iceberg?
Yes. Glue Data Catalog runs a native Iceberg REST catalog endpoint, supporting Iceberg table specs v1 and v2 by default, with v3 (deletion vectors, row lineage) added in November 2025. The same release added catalog federation to remote Iceberg-REST-compatible catalogs like Snowflake Polaris and Databricks Unity Catalog, so tables cataloged elsewhere can be queried through Glue without moving the data.
8. Can an AI agent query AWS Glue Data Catalog directly?
Not broadly yet. AWS announced a preview of business-context and semantic-search capabilities for Glue Data Catalog, along with a Glue Search API and a first-party MCP plugin for AI coding agents, in June 2026. As of this writing it’s Preview-only, live in four AWS regions (us-east-1, us-east-2, us-west-2, eu-west-1), and not a generally available capability. Outside of that preview, agents typically reach Glue’s metadata through the engines that already read it, like Athena, rather than querying the catalog conversationally.
