


The catalog is where an AI agent finds the right table to answer a business question; without it, the agent guesses. You have read the docs, spun up a Docker Compose, and sat through a demo or two, and you’re still not sure which open-source data catalog fits your team.
The hard part isn’t finding options; it’s comparing them honestly. Data catalog features look similar and every tool claims broad connector support. But the differences that matter are:
- How much infrastructure does each one needs
- What breaks during upgrades
- How much engineering time are you signing up for
Answers to these are buried in GitHub issues, not landing pages. Here are the top 5 tools, compared honestly, along with their key strengths and limitations:
| Tool | Best for | GitHub stars | First-party MCP server? | Key strength | Main limitation |
|---|---|---|---|---|---|
| DataHub (LinkedIn) | Federated architecture, large enterprises | 12,722 | Yes | Flexible metadata schema, column-level lineage, connector ecosystem | Infrastructure complexity (Kafka, Elasticsearch, multiple services) |
| OpenMetadata | Modern cloud-native stacks | 15,235 | Yes | Integrated discovery, quality, lineage, governance with 130+ connectors | Younger project; governance model still settling after the 2.0 release |
| Apache Atlas | Hadoop ecosystems | 2,141 | No (unofficial third-party wrappers only) | Mature governance, taxonomy, tag propagation, fine-grained access | Complex deployment; UI not modern |
| Marquez | Lineage and job/dataset dependency tracking | 2,281 | No | Real-time lineage via OpenLineage, pipeline traceability | Less focus on discovery or policy enforcement |
| OpenDataDiscovery (ODD) | ML and data science workflows | 1,428 | No | Federated search, metadata observability, ML tool integrations | Smaller community; features still under development |
GitHub star counts verified as of September 2026. The order has flipped since it was last checked: OpenMetadata now has more stars than DataHub. A first-party MCP server column matters more here than re-asserting a single #1 by star count.
Which open source data catalogs lead in 2026?
In 2026, DataHub and OpenMetadata both lead the open-source data catalog space, just not on the same axis. OpenMetadata now has more GitHub stars: 15,235 against DataHub’s 12,722, a reversal from the last check. DataHub still carries the deeper enterprise-deployment base: LinkedIn, Netflix, and Uber all run it at scale. Star count alone doesn’t settle which one leads. The sharper split: DataHub and OpenMetadata are also the only two of the five that ship a first-party MCP server, the interface that lets an AI agent query the catalog’s metadata directly instead of a person reading a web UI. That’s the more consequential fact for teams evaluating these tools with AI agents in mind.
The field is also narrowing, not growing. Amundsen, Lyft’s catalog, was historically grouped with DataHub and OpenMetadata as one of the “big three” open-source options. It was formally archived on September 10, 2026, and no credible new open-source entrant has appeared to take its place.
| Tool | Stars | Latest stable release | Contributors | First-party MCP server? | Activity level |
|---|---|---|---|---|---|
| DataHub | 12,722 | v1.7.0.1 | ~794 | Yes | Very high |
| OpenMetadata | 15,235 | 2.0.2-release | ~497 | Yes | Very high |
| Apache Atlas | 2,141 | release-2.5.0 | ~226 | No (unofficial only) | Moderate |
| Marquez | 2,281 | v0.50.0 | ~118 | No | Moderate |
| ODD Platform | 1,428 | v0.29.0 | ~45 | No | Low to moderate |
Marquez’s release date looks old, but the repository is still receiving commits as of mid-September 2026. It isn’t abandoned, it’s just not cutting new tags.
What are the best open source data catalogs? A deep dive
The best fit depends on your use case, not on popularity. Choose based on scale, stack complexity, and governance maturity: the five profiles below break down where each tool actually earns its place.
1. DataHub: Best for organizations that need modular metadata architecture, lineage, and federated governance.
DataHub evolved from LinkedIn’s internal tool, WhereHows, and celebrated its five-year anniversary with the launch of DataHub 1.0 in January 2025. The project hasn’t slowed since: the latest release, v1.7.0.1, shipped September 3, 2026, three minor versions past v1.4.0.
DataHub ships a documented, actively maintained MCP server (mcp-server-datahub) alongside an Agent Context Kit, giving agents direct access to its metadata. The capability isn’t new: v1.5.x added agent-context integration to the search CLI, and v1.6.0 and v1.7.0 hardened it further with policy targeting, optimistic locking, and assertion notes.
It’s an ideal choice if you have a platform engineering team of two or more comfortable managing Kafka, Elasticsearch, and Kubernetes; without that capacity, expect weeks of setup before you ingest your first metadata.
Standout features:
- Modular, service-oriented architecture supporting both push and pull metadata ingestion
- Interactive, column-level lineage graph with impact analysis
- Role-based access control for metadata
- Support for data contracts
- Wide connector ecosystem including Snowflake, BigQuery, dbt, Airflow, Databricks, and more.
- MCP Server and Agent Context Kit that let AI agents query metadata directly
Key limitations:
- Infrastructure complexity requires Kafka, Elasticsearch/OpenSearch, and multiple services
- Some integrations need custom engineering, making deployments resource-intensive
- Data quality and observability features continue evolving in the open source edition
Latest release: v1.7.0.1, September 2026. (GitHub)
DataHub’s architecture runs several interconnected services your team should plan for:
Infrastructure prerequisites
| Component | Purpose | Notes |
|---|---|---|
| Apache Kafka | Real-time metadata event streaming | Core dependency; handles MetadataChangeProposal events |
| Elasticsearch or OpenSearch | Search indexing | OpenSearch 2.19.3+ required for semantic search (v1.4.0) |
| MySQL or PostgreSQL | Primary metadata store | Stores aspect data and system metadata |
| DataHub GMS | Metadata service backend | Central API layer |
| DataHub Frontend | React-based web UI | Separate container |
| Schema Registry | Schema management for Kafka | Required for metadata serialization |
Most production deployments run on Kubernetes with Helm charts; Docker Compose suffices for evaluation only.
What users like:
DataHub’s redesigned lineage navigator in v1.4.0 drew a positive community response, adding summary tabs for domains, glossary terms, and data products. Monthly town halls and an openly published 2025 roadmap reinforce that trust.
What needs improvement:
Operational complexity is the most frequently reported pain point on GitHub, most visibly around version upgrades: see “Your upgrade blocks your roadmap” and “A routine version bump turns into weeks of investigation” below for two concrete examples.
2. OpenMetadata: Best for teams seeking a unified metadata platform covering governance, lineage, and collaboration
Unlike DataHub’s modular, teams-assemble-it architecture, OpenMetadata ships a unified platform covering discovery, governance, quality, profiling, lineage, and collaboration in one package.
Built by the team behind Uber’s data infrastructure, along with the founders of Apache Hadoop and Atlas, OpenMetadata launched with a clear thesis: metadata management shouldn’t require five different tools stitched together. The project’s GitHub stars nearly doubled this year, from roughly 8,700 to 15,235, and it crossed a major version line, 1.x to 2.0, on August 24, 2026, with two fast-follow maintenance releases since.
OpenMetadata suits teams with one to two platform engineers who want a broad feature set without a complex infrastructure stack, making it a practical choice for mid-size organizations or startups building their first metadata layer.
Standout features:
- Built-in data quality tests and data profiling
- Data Contracts for producer-consumer collaboration
- MCP server for AI agents, hardened further in the 2.0 line
- Collaboration features, including comments, domain glossaries, tasks, and announcements
- Simplified architecture (MySQL/PostgreSQL + Elasticsearch) compared to DataHub’s multi-component stack
- 130+ connectors, self-reported
Key limitations:
- The 2.0 release changed the governance model itself: direct team membership now routes through Group teams. Check OpenMetadata’s current governance docs before assuming last year’s RBAC read still holds.
- Some connectors need customization for edge cases
- Performance at a very large enterprise scale requires tuning
Latest release: 2.0.2-release, September 16, 2026 (GitHub)
Infrastructure prerequisites
OpenMetadata runs a leaner stack compared to DataHub:
| Component | Purpose | Notes |
|---|---|---|
| MySQL or PostgreSQL | Metadata store | Primary backend; no graph database required |
| Elasticsearch | Search and indexing | Standard deployment |
| OpenMetadata Server | Java-based API and UI server | Single application handles both backend and frontend |
| Airflow (optional) | Ingestion workflow orchestration | Can use the built-in scheduler or external Airflow |
The absence of Kafka and a graph database simplifies deployment enough to get a working instance running in a single afternoon for evaluation.
What users like:
OpenMetadata kept the same patch cadence through the 2.0 line: 2.0.1 and 2.0.2 both landed within three weeks of the August 24, 2026 major release, each shipping further MCP hardening alongside the usual bug fixes.
What needs improvement:
- Advanced RBAC remains a gap for larger enterprises. A June 2025 feature request asks for customizable ownership roles, granular per-property edit permissions, and federated role management.
- Stability under high concurrency has also surfaced as a concern: see “Your catalog silently breaks your pipelines” below for the specific failure mode.
3. Apache Atlas: Best for organizations heavily invested in Hadoop ecosystems needing strong metadata governance
Several vendors build on Apache Atlas as their metadata backend, including Atlan, the Context Layer for AI, which runs on a hardened fork of it.
Originally developed by Hortonworks and donated to Apache, Atlas was among the first open source Hadoop metadata governance tools, powered by JanusGraph, Apache Solr, Apache Kafka, and deep Apache Ranger integration for fine-grained access control. The project keeps moving: release-2.5.0, tagged April 21, 2026, added an async import API, a Trino metadata extractor, Postgres as a JanusGraph storage option, Hadoop 3.4.2 and HBase 2.6.4 upgrades, TLS 1.3, and a UI migration off Backbone.js onto React, with 2.6.0 still at release-candidate stage.
It’s a strong fit for Hadoop-ecosystem teams familiar with HBase, Solr, and Kafka administration; on Snowflake, BigQuery, or Databricks, it will require significant custom extension work. And if an AI agent needs to query the catalog directly, Atlas is the one tool on this list with a real gap: no official first-party MCP server, only unofficial, community-built third-party wrappers with no Apache Software Foundation backing.
Standout features:
- Rich support for taxonomy, classifications, and tag propagation
- Fine-grained metadata access controls and audit tracking
- Deep integrations with the Hadoop stack (Hive, Kafka, HBase)
- Powered by JanusGraph, Apache Solr, Apache Kafka, and Apache Ranger
- Well-documented via the Apache Software Foundation’s Jira project
Key limitations:
- Less focus on discovery workflows for end users
- Heavy and complex to deploy and maintain
- UI feels dated compared to modern alternatives
- Adapting to modern cloud or lakehouse architectures requires custom extensions
- Complex setup for non-Hadoop environments
- No official first-party MCP server; only unofficial third-party wrappers exist
Latest release: release-2.5.0, April 2026 (GitHub)
Infrastructure prerequisites
The infrastructure footprint is the heaviest of any tool here, typically requiring a Hadoop cluster or equivalent.
| Component | Purpose | Notes |
|---|---|---|
| Apache Kafka | Event notifications and hooks | Required for real-time metadata capture |
| Apache Solr | Search indexing | Full-text search across entities |
| JanusGraph | Graph metadata store | Stores entity relationships and lineage |
| Apache HBase (or BerkeleyDB) | JanusGraph storage backend | HBase for production; BerkeleyDB for evaluation; PostgreSQL is now a supported option as of release-2.5.0 |
| Apache Ranger (optional) | Policy enforcement | Integrates with Atlas for tag-based access control |
What users like:
Atlas’s governance depth remains unmatched for Hadoop environments, with classification inheritance flowing automatically through lineage paths.
What needs improvement:
- Deployment complexity is a persistent concern: a blog post on building Atlas v2.3.0 describes “fumbling” through installation from a lack of documentation, and the same challenges persist outside Hadoop even with release-2.5.0’s upgrades.
- A security vulnerability (CVE-2024-46910) disclosed in February 2025 exposed XSS issues in Atlas 2.3.0 and earlier, fixed in v2.4.0; harder to stay ahead of given Atlas’s slower cadence versus DataHub and OpenMetadata’s weekly patches.
4. Marquez: Best for teams focused on lineage, provenance, and job/dataset dependency tracking
If your primary question is “how does data move through our pipelines, and what breaks when something changes?” Marquez answers it with less infrastructure than other tools on this list.
Created by WeWork and now a graduated LF AI & Data Foundation project, Marquez also pioneered OpenLineage, the open standard for data lineage metadata collection, and as its reference implementation works out of the box with every OpenLineage integration: Apache Airflow, Apache Spark, Apache Flink, dbt, and Dagster.
Marquez fits data engineering teams that already use Airflow, Spark, or dbt and need real-time lineage without investing in a full catalog platform. It’s also the one tool of the five with no public move toward an agent-facing interface, though that’s not necessarily a knock: Marquez is scoped to lineage, and a lineage-only tool doesn’t automatically need one.
When to pair Marquez with another tool
Marquez excels at lineage but does not replace a catalog: teams needing discovery, search, glossaries, governance, or quality monitoring should pair it with DataHub, OpenMetadata, or a commercial platform, since both DataHub and OpenMetadata can consume its OpenLineage events directly.
Standout features:
- OpenLineage-compliant metadata server for real-time lineage collection and visualization
- Unified metadata UI showing job-to-dataset relationships and execution lineage
- Flexible lineage API for automating impact analysis, backfills, and root-cause tracing
- Integration with modern data stack tools like dbt and Apache Airflow
- New Data Observability dashboard and GraphQL endpoint (beta) in v0.50.0
Key limitations:
- Less emphasis on discovery or governance beyond lineage
- Not feature-rich in policy enforcement, access control, or business metadata
- Smaller community and ecosystem compared to DataHub or OpenMetadata
- No MCP server or agent-facing interface, unlike DataHub and OpenMetadata
Latest release: v0.50.0, October 2024, still current as of September 2026. (GitHub)
Infrastructure prerequisites
Marquez runs the leanest stack of any tool on this list:
| Component | Purpose | Notes |
|---|---|---|
| PostgreSQL | Metadata and lineage event store | Only required database |
| Marquez API server | Java-based backend | Handles OpenLineage event ingestion and API queries |
| Marquez Web UI | React-based frontend | Lineage visualization and dataset browsing |
What users like:
The OpenLineage standard itself is Marquez’s strongest differentiator, for the reasons above.
What needs improvement:
The GitHub issues page shows a slower response time than DataHub or OpenMetadata. As of early 2026, open issues dating back to May 2025 remain unaddressed.
5. OpenDataDiscovery: Best for organizations needing federated search and metadata discovery with a focus on ML workflows.
Most open source catalogs treat ML metadata as an afterthought behind tables and dashboards, with models, experiments, and feature stores bolted on later, if at all. OpenDataDiscovery (ODD) flips that priority.
Developed by Provectus around 2021, ODD was initially designed for ML teams but later expanded to cover data engineering and data science use cases. Its federated architecture uses lightweight collector agents that push metadata to the platform via REST API, avoiding the need for a centralized ingestion orchestrator.
If your organization’s primary concern is understanding how data flows from ingestion through ML model training and into production, ODD addresses that niche. Its own README doesn’t mention MCP, Model Context Protocol, or any agent-facing query interface. If AI-agent access matters to your evaluation, treat that as a gap today, not an assumption to fill in.
Standout features:
- Federated data catalog enabling search across data silos
- Ingestion-to-product data lineage
- Metadata health and observability dashboards
- End-to-end microservices lineage
- Integration with data quality tools and ML platforms, including dbt, Snowflake, SageMaker, KubeFlow, and BigQuery
- Available on AWS Marketplace
Key limitations:
- Less community maturity and adoption compared to older projects
- Some features (lineage depth, quality) remain under development
- Connectors and integrations may require custom work
- No MCP or agent-facing interface documented anywhere in the project
Latest release: v0.29.0, June 2026 (GitHub)
Infrastructure prerequisites
ODD’s architecture is straightforward:
| Component | Purpose | Notes |
|---|---|---|
| PostgreSQL | Metadata store | Only required database |
| ODD Platform | Java-based backend and UI | Single application container |
| ODD Collectors | Metadata ingestion agents | Separate containers per data source type |
What users like:
ML engineers value ODD’s first-class treatment of ML entities. The GitHub repository describes how ODD operates ML entities as “first citizens,” integrating model metadata alongside traditional data assets.
What needs improvement:
The small community is the biggest risk factor. The issues page shows limited activity through 2025, with several-month gaps between bug reports.
The operational reality of open source catalogs
Catalog becomes a second product
Three to six months of engineering effort is the standard estimate for deploying an open-source catalog. What that number hides: the catalog starts as a project and quietly becomes a product. Not because the tools are bad; running distributed infrastructure in production surfaces problems only your team can solve. Three examples, drawn directly from community-reported issues:
Your upgrade blocks your roadmap
A DataHub user upgrading to v1.2.0 found that hard-deleting aspects and restoring Elasticsearch indices had become three to four times slower than in v1.1.0, forcing an unplanned debugging sprint.
A routine version bump turns into weeks of investigation
A separate DataHub issue from September 2025 describes the upgrade reindex job getting stuck in a loop even after the recommended workaround, leaving teams with large indices facing a multi-day debugging cycle whose fix lives in GitHub threads, not a support queue.
Your catalog silently breaks your pipelines
An OpenMetadata issue from August 2025 documents a more insidious failure: the server becomes unresponsive under high concurrent load, and the Airflow Lineage Backend hangs indefinitely. The reporting team spent months on load testing, retry PRs, and Helm chart scaling before finding the root cause: a missing read timeout let a connected but unresponsive server block Airflow tasks indefinitely.
None of this means these tools are bad. But each issue is a cost. In a managed platform, it’s the vendor’s problem. In open source, it’s yours.
The real cost of “free”: A back-of-napkin calculation
Open-source catalogs have no licensing fees. But “free” has a price tag, distributed across payroll and infrastructure budget where it’s harder to see. Here’s what a typical deployment actually costs in Year 1:
| Cost category | Estimate | Basis |
|---|---|---|
| Engineering time (deployment) | $90,000–$135,000 | 2 engineers × 3–6 months at ~$180K loaded cost, 50% allocation |
| Engineering time (ongoing ops) | $54,000–$108,000/year | 1–2 engineers × 30% time on upgrades, connector fixes, debugging |
| Infrastructure | $24,000–$60,000/year | Kafka, Elasticsearch, Kubernetes clusters, database, and monitoring |
| Opportunity cost | Hard to quantify | Features not built, governance workflows not automated, adoption delayed |
| Year 1 total (excluding opportunity cost) | $168,000–$303,000 |
These numbers shift with your cloud provider, salaries, and deployment complexity, but they’re directionally right for a mid-size organization running DataHub or OpenMetadata in production. Run this calculation with your own numbers before choosing open source; if the total surprises you, that’s the conversation worth having.
How can you pick and deploy an open source data catalog?
Pick and deploy an open-source data catalog in six steps, from defining must-haves through planning for long-term ownership.
Step 1: Define must-have capabilities
Identify the non‑negotiables for your environment:
- Metadata scope
- Lineage depth
- Governance controls (RBAC, tags, classification, etc.)
- Business glossary
- Connector coverage
- Scalability and architecture
Step 2: Evaluate open-source health and community
Shortlist catalogs with active communities, solid documentation, and frequent releases, scoring each on:
- GitHub metrics: Stars, forks, contributors, release cadence.
- Community responsiveness: Activity on Slack, GitHub Issues, or mailing lists.
- Documentation and setup guides: Are they maintained and easy to follow?
- License type: Apache 2.0, MIT, or custom. This determines flexibility for enterprise deployment.
- Agent access: If an AI agent needs to query the catalog directly, rather than a person reading a web UI, check whether the project ships a first-party MCP server. Today, only DataHub and OpenMetadata do.
Step 3: Pilot in a high-impact domain/use case
Pilot your top choice in a sandbox with one high‑value domain (customer, finance, or marketing), testing discovery, search accuracy, lineage visualization, glossary tagging, and ownership visibility with both technical and non‑technical users early.
Step 4: Automate ingestion and policy enforcement
Automate metadata ingestion via tools like Airflow, dbt, Prefect, or Dagster, and implement tag‑driven or role-based access control so governance runs automatically. For advanced setups, connect catalogs to CI/CD pipelines or APIs for version-controlled metadata updates.
Step 5: Measure adoption, reliability, and ROI
Track early adoption: search volume, active users, issue resolution speed. If results are strong, expand gradually. If not, reassess or test your runner-up tool.
Step 6: Plan for sustainability
Open source catalogs often require internal ownership. Document:
- Time spent on setup, upgrades, and maintenance
- Custom code or connectors built internally
- Cost of infrastructure vs. potential managed alternatives
This builds a baseline for future ROI comparisons against a managed platform.
Quick reference by use case:
| Use case | Recommended tool(s) | Reason |
|---|---|---|
| Discovery-first | OpenMetadata, DataHub | Strong search UX, broad connector support |
| Governance-heavy | Apache Atlas, DataHub | Tag propagation, RBAC, audit trails |
| Lineage-focused | Marquez, DataHub | OpenLineage compliance, column-level lineage |
| ML workflows | ODD, OpenMetadata | SageMaker/KubeFlow integrations, metadata observability |
| Hadoop ecosystem | Apache Atlas | Native Hive/HBase/Kafka hooks |
| Modern cloud-native | OpenMetadata, DataHub | Snowflake, BigQuery, dbt, Airflow connectors |
| AI-agent access | DataHub, OpenMetadata | Only two with a first-party MCP server |
What are the trade-offs of choosing an open source data catalog?
An open-source data catalog gives you control, but your team handles the work. Here’s how the benefits and trade-offs map against each other, and how to mitigate the risks:
| Benefit | Trade-off | Mitigation strategy |
|---|---|---|
| No licensing fees | Infrastructure and personnel costs add up | Budget for 1-2 FTE engineers dedicated to catalog operations |
| Full customization | Custom code requires ongoing maintenance | Contribute upstream to reduce fork divergence |
| No vendor lock-in | Migration between tools is still complex | Use OpenLineage and open APIs for portability |
| Community innovation | Support is best-effort, not SLA-backed | Build internal expertise; engage actively in Slack/GitHub |
| Transparency (open code) | Security patches depend on community responsiveness | Monitor CVEs; maintain internal patching capability |
| Self-hosted control | You own uptime, scaling, and disaster recovery | Invest in infrastructure automation (Helm, Terraform) |
According to Gartner, poor data quality costs organizations an average of $12.9 million per year. Whether you choose open source or managed, the cost of doing nothing is higher than either option.
Should you go open source or managed?
Six questions to make the call:
Q1. Do you have 2+ platform engineers who can dedicate 30%+ of their time to catalog operations? No means open source will likely stall after the pilot; evaluate Atlan or a similar managed platform first.
Q2. Production experience operating Kafka, Elasticsearch, and Kubernetes? Yes makes DataHub and OpenMetadata viable. Learning it adds 3–4 months on top of deployment. If it’s simply not your focus, the overhead will compete with core engineering work, so consider a managed platform.
Q3. Is your need narrow (lineage only) or broad (discovery, governance, lineage, and quality)? Lineage only points to Marquez, lightweight and OpenLineage-native; pair with a catalog later if needs expand. Broad points to DataHub or OpenMetadata, though broad needs mean broad maintenance, so if you need all four live within 90 days, a managed platform gets you there faster.
Q4. Is your stack primarily Hadoop-based? If yes, Apache Atlas remains the strongest fit for its unmatched Hadoop governance depth; if no, skip it, since it will require significant custom work.
Q5. Is ML metadata (models, experiments, feature stores) a primary concern? If yes, evaluate ODD alongside OpenMetadata and expect a smaller community and custom collector work; if no, focus on DataHub or OpenMetadata for general-purpose cataloging.
Q6. What’s your acceptable time-to-value? Under 90 days points to a managed platform like Atlan; open source typically needs 3–6 months to reach production-ready value. Six-plus months is fine if you passed the checks above.
Open source vs. Atlan: A side-by-side snapshot
Open source catalogs work well for specific tasks like discovery, lineage, and search, but you usually have to build governance, integrations, and user workflows yourself. Atlan provides a unified control plane across data and AI tools, so your team can focus on insights rather than managing systems.
| Dimension | Open source catalogs | Atlan |
|---|---|---|
| Deployment | Self-hosted; you manage infrastructure | Managed SaaS; Atlan handles operations |
| Connectors | Varies by tool | 100+ pre-built connectors |
| Governance | Built piecemeal across tools | Unified governance with automated policies |
| Lineage | Column-level available in DataHub, OpenMetadata, and Marquez | Column-level lineage across data and AI assets |
| Collaboration | Varies; some offer comments and glossaries | Embedded collaboration with Slack, Jira, and email integrations |
| AI governance | Limited or emerging | Purpose-built AI governance for model lineage and compliance |
| Time to value | Months of engineering effort | Weeks with pre-built workflows |
| Support | Community-driven (Slack, GitHub) | Enterprise SLA with dedicated support |
Companies like Nasdaq, Autodesk, General Motors, and Fox use Atlan to govern their data and AI programs at scale.
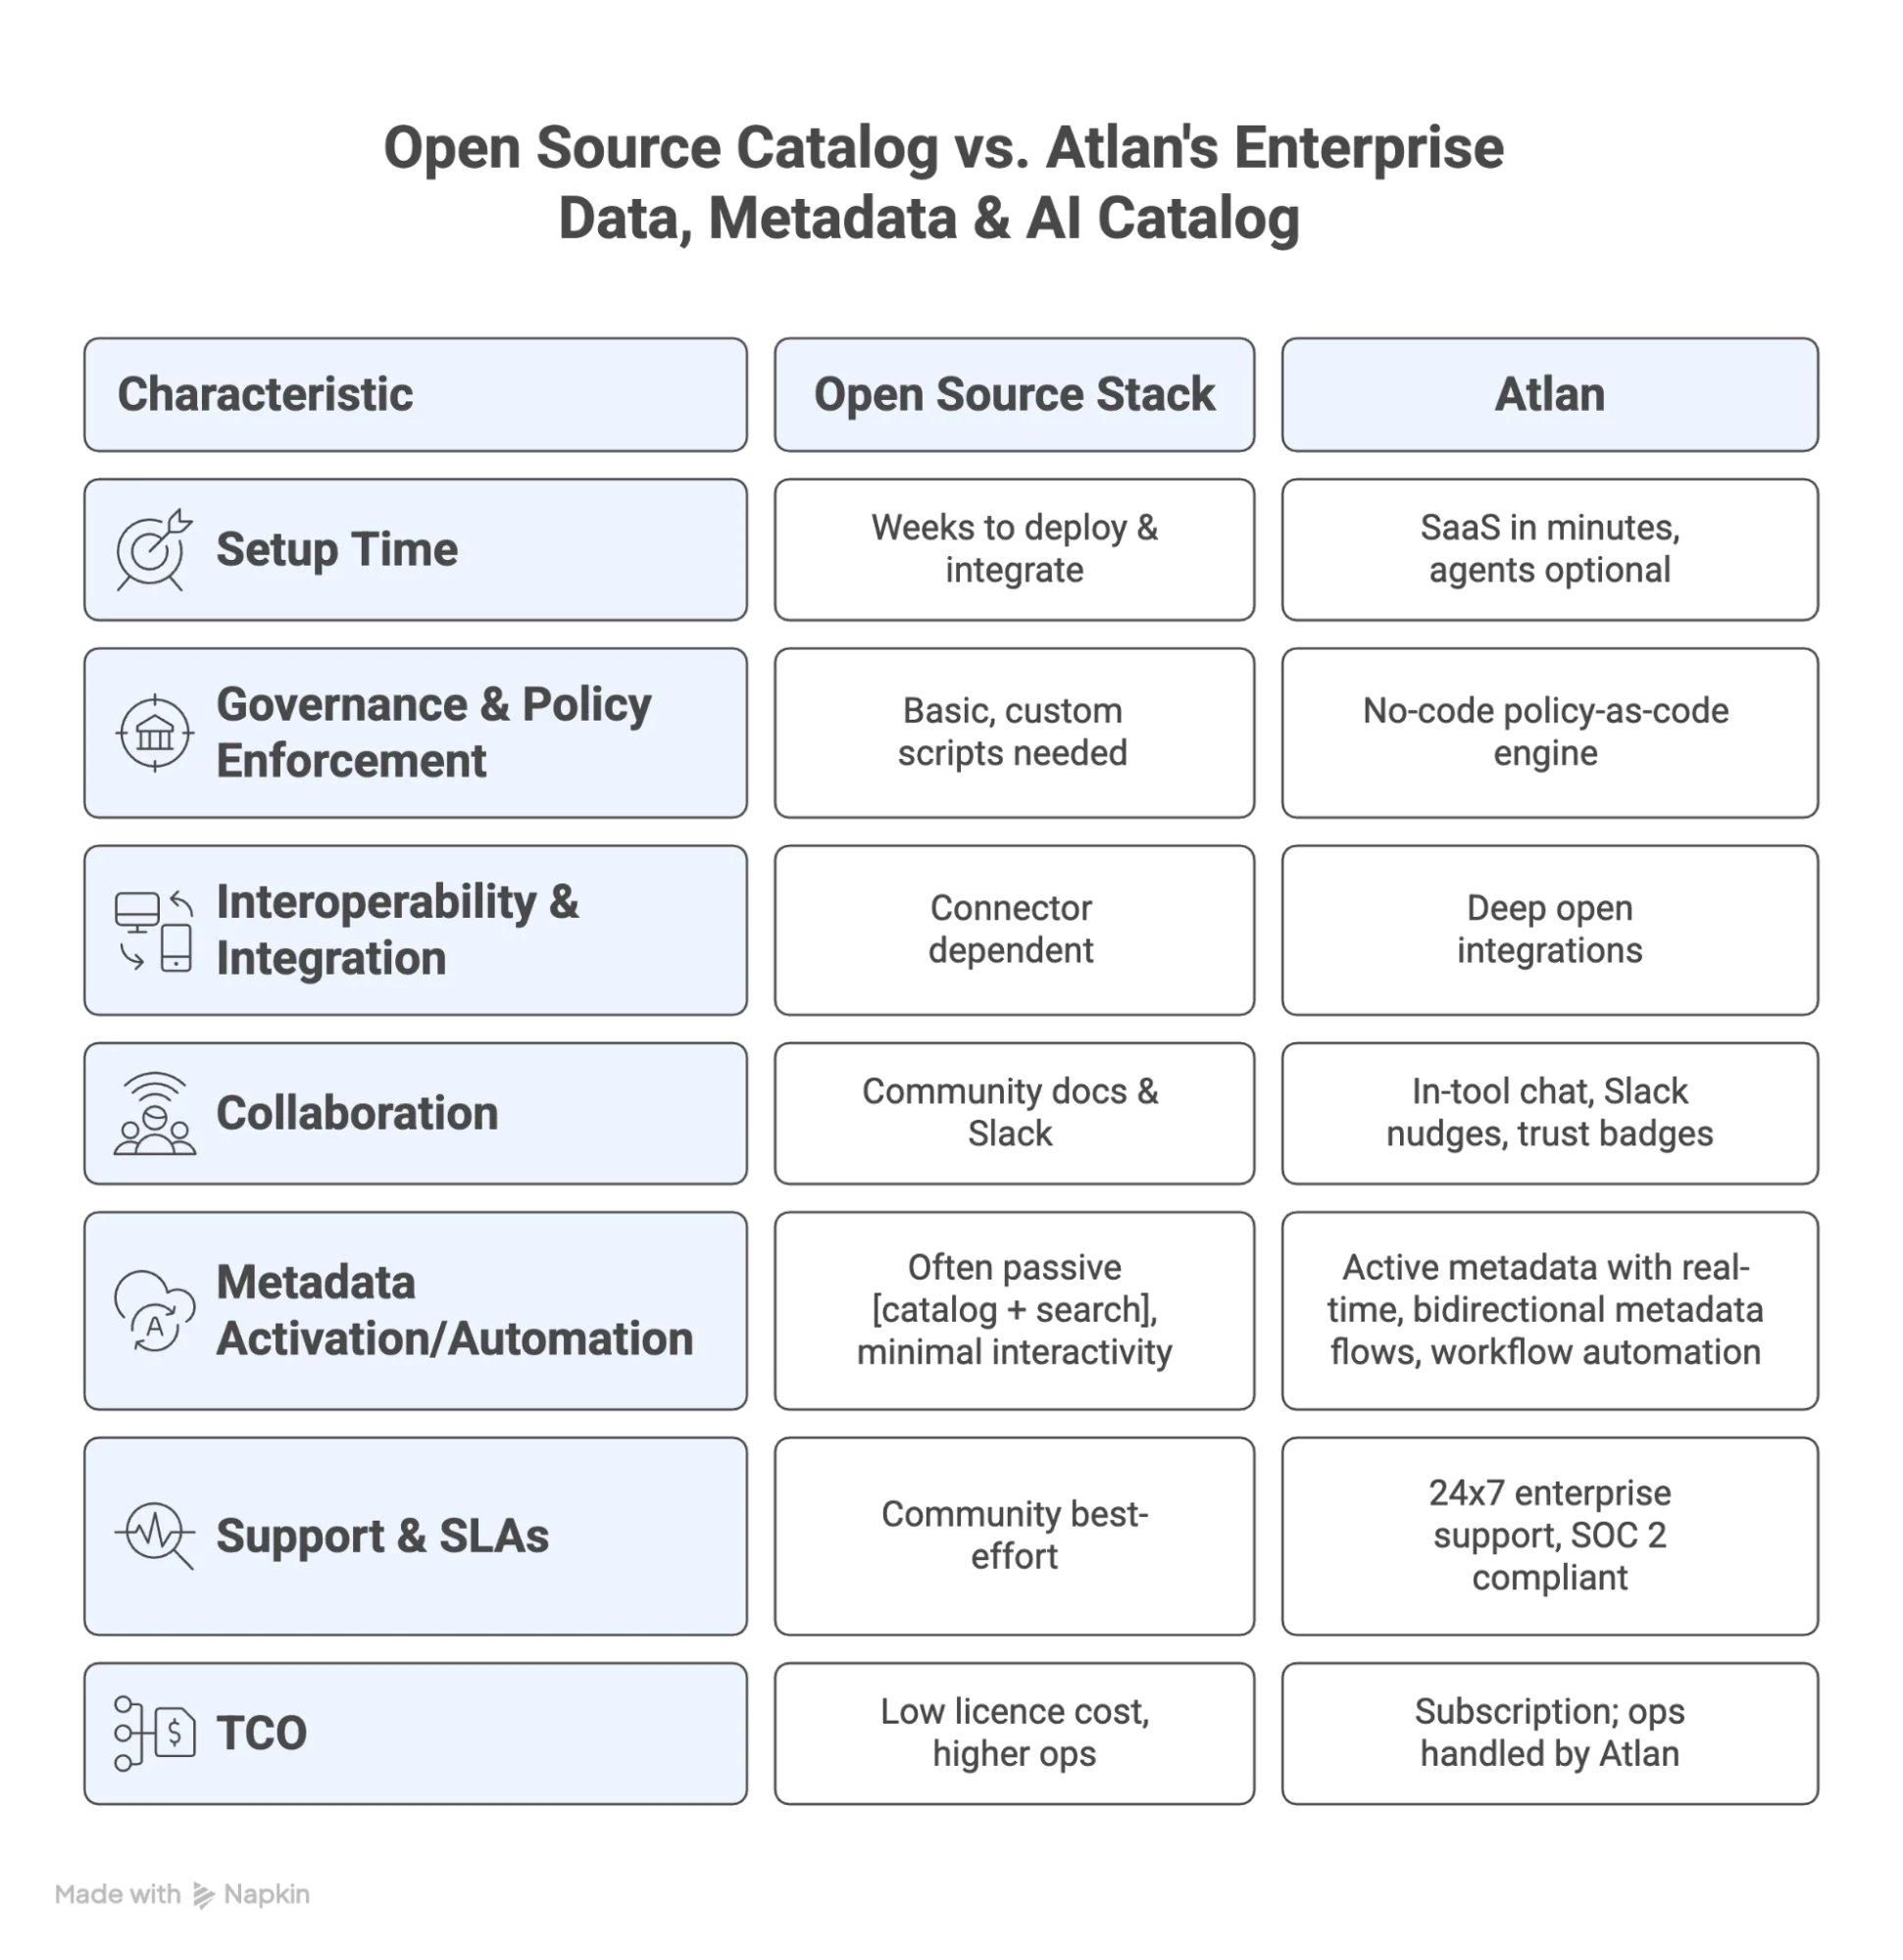
Open source vs. Atlan: Side-by-side snapshot in 2026. Source: Atlan.
Ready to move from DIY scripts to modern, automated data cataloging?
Open source data catalog software has matured significantly, but maturity has limits: every tool here still requires engineering investment for deployment, maintenance, and feature development. If your team has the platform engineering muscle, that gives you control and flexibility. If you’re hitting the walls of maintenance overhead, connector gaps, or governance complexity, a managed platform like Atlan helps accelerate your program without sacrificing depth.
FAQs about open source data catalog tools
1. What is an open source data catalog?
A free, community-maintained tool for discovering, documenting, and managing metadata across your data ecosystem: searchable metadata, lineage tracking, glossaries, and API extensibility, self-hosted for full control over customization and security.
2. How can an open source data catalog improve data discovery?
It centralizes metadata from disparate systems into a single searchable interface, reducing the time data teams spend finding and understanding assets.
3. What are the benefits of using an open source data catalog for data governance?
Classification, tagging, ownership assignment, and policy enforcement without licensing costs. Apache Atlas and DataHub, in particular, offer fine-grained access controls and audit trails.
4. How do I choose the right open source data catalog for my organization?
Match the tool to your stack: Atlas for Hadoop, DataHub or OpenMetadata for modern cloud-native environments. Prioritize connector coverage, lineage depth, and governance controls, and run a 30-day pilot in one business domain before committing.
5. What features should I look for in an open source data catalog?
Metadata coverage across your existing tools, column-level lineage, governance and access control, search and discovery UX, API extensibility, community health, and, if an AI agent needs to query the catalog directly, whether the project ships a first-party MCP server.
6. What is the difference between open source and commercial data catalogs?
Open source trades licensing fees for infrastructure management, connector development, and ongoing maintenance; commercial catalogs trade that work for enterprise support, faster deployment, and managed infrastructure. Teams with dedicated platform engineering often succeed with open source; those prioritizing time-to-value typically choose commercial.
7. How much engineering effort does deploying an open source catalog require?
Three to six months for initial deployment (infrastructure, connectors, ingestion pipelines, onboarding), plus ongoing DevOps time. Organizations typically allocate one to two full-time engineers for catalog operations at scale.
8. Can open source catalogs handle enterprise-scale deployments?
Yes, when properly architected: LinkedIn, Netflix, and Uber all run DataHub or OpenMetadata at massive scale, though smaller organizations may find managed platforms more cost-effective.
9. When should I choose Atlan over open source alternatives?
When you need unified governance across data and AI, faster time to value, or your platform engineering capacity is limited. Many organizations start with open source and transition to managed platforms as governance complexity grows.
10. What is column-level lineage, and which open source catalogs support it?
It tracks individual field transformations through your pipeline, showing how specific columns change from source to destination, which enables precise impact analysis and debugging. DataHub, OpenMetadata, and Marquez all offer it.
11. Do open source data catalogs support MCP or AI agents?
DataHub and OpenMetadata each ship a first-party MCP server, so an AI agent can query the catalog’s metadata directly. Apache Atlas has no official MCP server, only unofficial third-party wrappers with no Apache Software Foundation backing. Marquez and OpenDataDiscovery have made no public move toward an agent-facing interface as of September 2026.
